
Network Monitoring / NOC Best Practices for Reliable IT Operations
Your network runs every part of your business, so you need constant visibility into its health, performance, and security. Network monitoring and a Network Operations Center (NOC) give you that oversight by tracking systems 24/7 and responding to issues before they disrupt operations. A Network Operations Center (NOC) is a centralized team and toolset that monitors, manages, and maintains your network around the clock to ensure availability, performance, and reliability.
When you understand how a NOC functions, you see how it detects incidents, coordinates responses, and keeps infrastructure stable across on‑premises and cloud environments. You also gain clarity on the tools that power monitoring, alerting, traffic analysis, and performance management.
As networks grow more complex, you must adopt modern operational practices and stronger risk controls to stay ahead of outages and threats. A closer look at core functions, essential technologies, and practical security strategies shows you how to build a monitoring approach that supports long‑term operational excellence.
Core Functions of a Network Operations Center
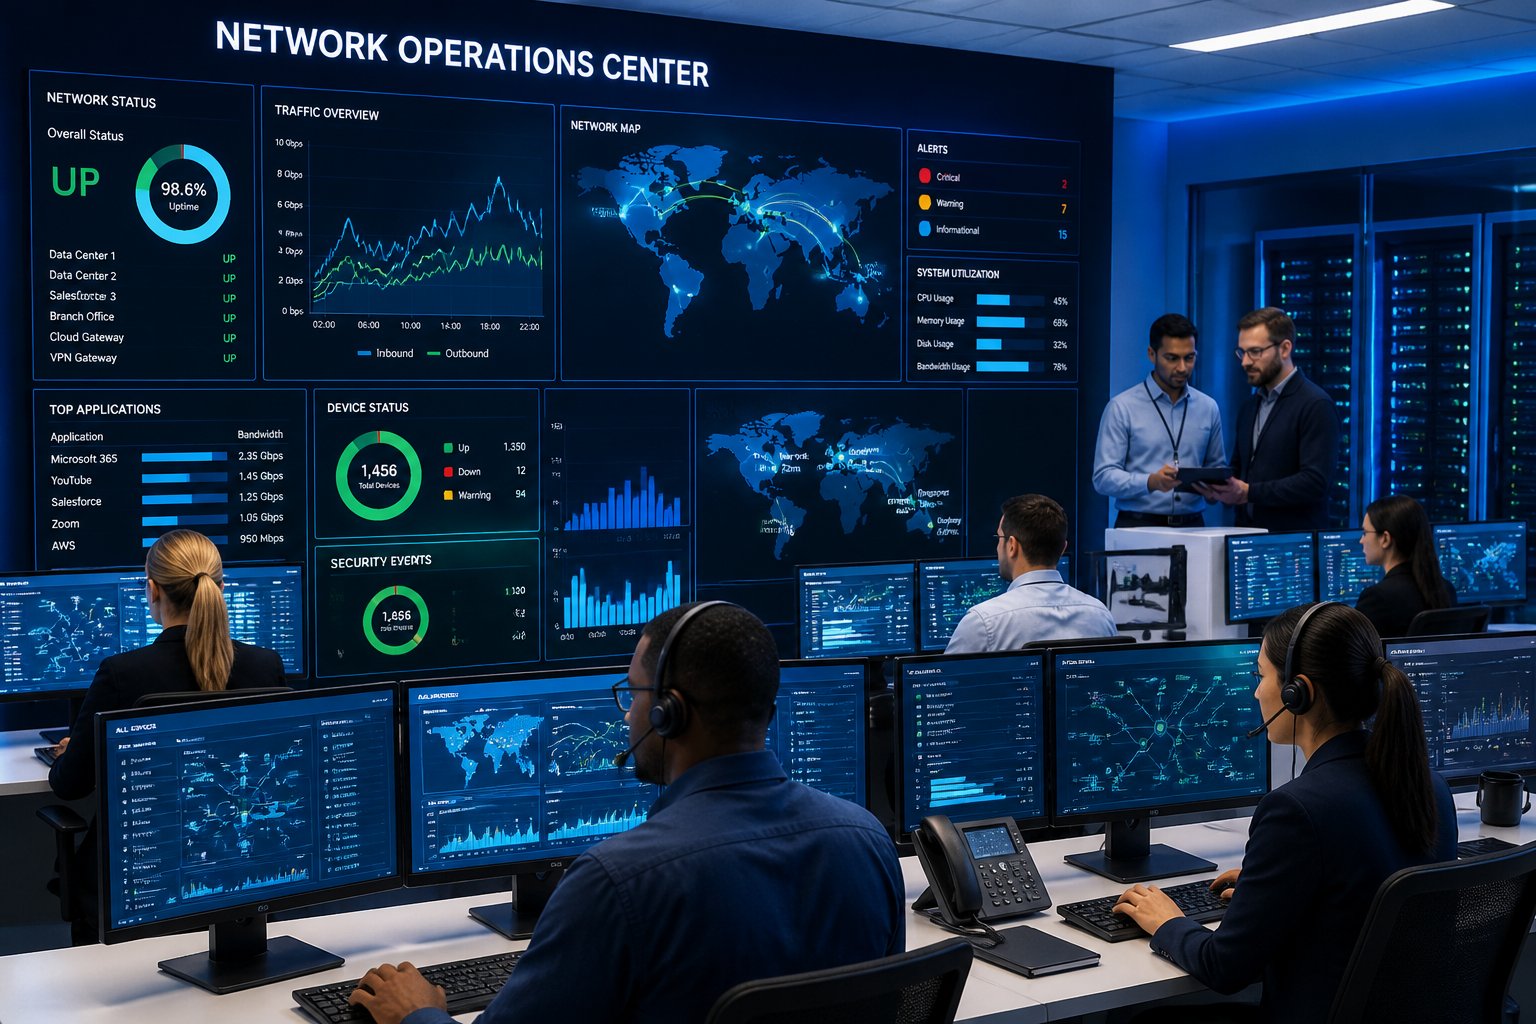
A network operations center (NOC) protects your infrastructure through continuous visibility, structured incident management, and disciplined uptime practices. You rely on the NOC team to detect issues early, resolve them quickly, and keep critical services available around the clock.
Real-Time Performance Tracking
Your NOC delivers 24/7 monitoring of routers, switches, firewalls, servers, cloud workloads, and endpoints. NOC engineers use real-time monitoring tools to track metrics such as bandwidth utilization, latency, packet loss, CPU load, memory usage, and interface errors.
Dashboards and alerting systems highlight threshold breaches the moment they occur. This allows your team—or a NOC support provider—to act before minor degradation becomes an outage.
Key monitoring activities include:
-
- Continuous log collection and analysis
- SNMP and flow-based traffic monitoring
- Application and service health checks
- Capacity tracking and trend reporting
You gain visibility into performance baselines and long-term trends. That data supports capacity planning, change validation, and risk reduction across your environment.
Incident Response and Resolution
When alerts trigger, the NOC team moves immediately into structured incident response. Clear escalation paths and predefined runbooks guide each step, from initial triage to full incident resolution.
NOC engineers classify incidents by severity and business impact. They isolate affected systems, perform root cause analysis, and apply corrective actions such as configuration rollbacks, service restarts, or traffic rerouting.
A disciplined incident management process focuses on:
-
-
-
- Fast detection and acknowledgment
- Accurate impact assessment
- Coordinated communication
- Documented remediation steps
-
-
You measure performance through metrics like mean time to repair (MTTR) and incident frequency. Lower MTTR reflects efficient workflows, skilled staff, and well-maintained documentation.
If you operate an iNOC or use outsourced NOC services, you still retain visibility through detailed reporting and ticketing integration.
Ensuring High Availability of Services
High availability requires more than reactive support. Your network operations center enforces proactive controls that reduce downtime and protect service continuity.
NOC engineers monitor redundancy mechanisms such as failover clusters, load balancers, and backup links. They verify replication status, test disaster recovery procedures, and confirm that backup systems remain operational.
To maintain uptime, the NOC focuses on:
-
-
-
- Verifying redundant paths and power systems
- Monitoring SLA compliance
- Managing patch schedules and maintenance windows
- Coordinating planned changes to avoid service disruption
-
-
You benefit from continuous oversight that keeps systems stable and predictable. With consistent NOC support, your critical applications and connectivity remain accessible to users without unnecessary interruption.
Essential Tools and Technologies
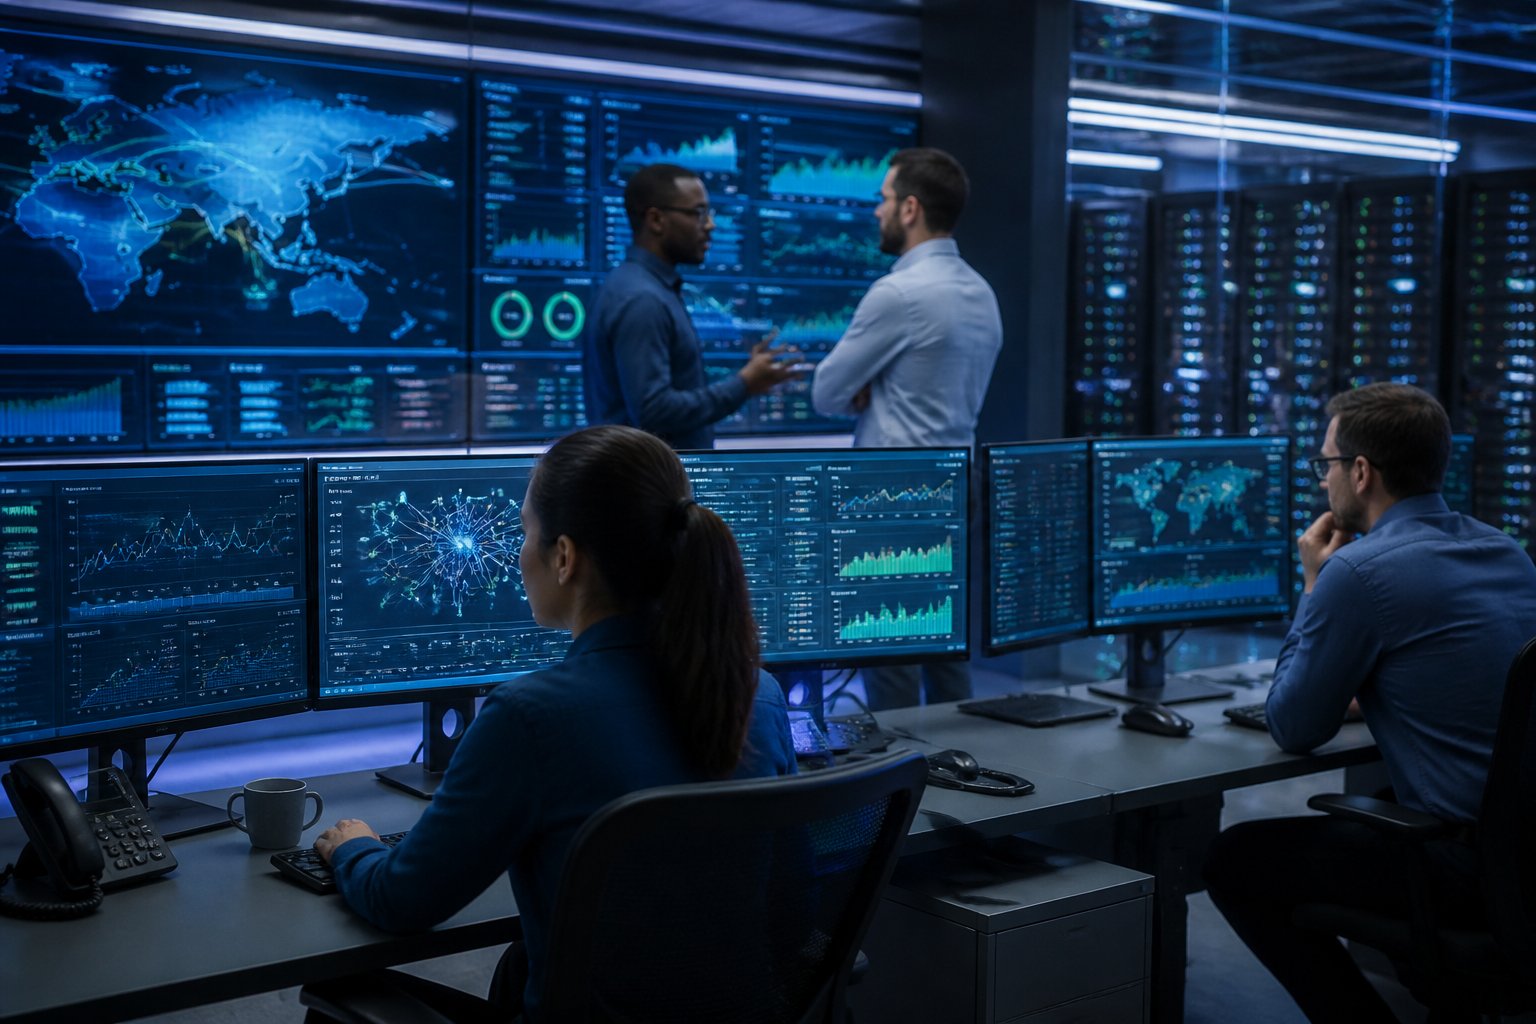
Effective NOC monitoring depends on centralized visibility, automated response, and deep integration across network, application, and cloud layers. You need tools that collect accurate data, correlate events, and present clear insights without adding operational overhead.
Unified Dashboards and Single Pane of Glass
You need a single pane of glass that aggregates data from network devices, servers, applications, and cloud services into one NOC dashboard. A unified view reduces context switching and speeds up incident response.
Modern network monitoring tools such as SolarWinds NPM, PRTG, LogicMonitor, and OpenNMS consolidate metrics from SNMP, WMI, NetFlow, APIs, and custom collectors. Some platforms use distributed collectors or minions to gather data from remote sites and cloud environments, then forward it to a centralized NMS.
A well-designed dashboard should display:
-
-
-
- Device health and availability
- Bandwidth monitoring and NetFlow analyzer data
- Application monitoring and APM metrics
- Active alerts with severity levels
- Capacity trends and SLA indicators
-
-
Strong event correlation and alert correlation reduce noise by grouping related alarms into a single incident. Instead of reacting to dozens of device alerts, you see one root-cause issue tied to a failed switch or saturated link.
This structure helps you identify bandwidth hogs, failing interfaces, or high-latency paths quickly using tools like ping tests, traffic analyzers, and performance charts.
Automation and Workflow Optimization
Manual ticket triage slows your response time. You improve consistency and speed by implementing automated workflows that trigger actions based on defined thresholds and policies.
Modern NOC monitoring tools integrate with ITSM platforms and CMDB systems to enrich alerts with asset data. When a router fails, the system can automatically create a ticket, assign it to the correct team, and attach device history.
Common automation use cases include:
-
-
-
- Restarting services when application monitoring detects failure
- Executing scripts when CPU or memory thresholds exceed limits
- Triggering patch management workflows
- Escalating unresolved alerts after defined time intervals
-
-
Advanced platforms like Dynatrace and New Relic use intelligent analysis to reduce false positives and prioritize actionable incidents. Alarm correlation ensures you focus on root causes rather than symptoms.
By combining troubleshooting tools with workflow engines, you reduce mean time to detect (MTTD) and mean time to resolve (MTTR) without increasing staffing.
Proactive Security and Anomaly Detection
Reactive monitoring exposes you to avoidable outages and security risks. You strengthen resilience by detecting anomalies before users report issues.
A modern NOC monitoring tool analyzes historical baselines for traffic, latency, and application response times. When behavior deviates from normal patterns, the system flags it for review.
Key capabilities include:
-
-
-
- NetFlow analyzer insights to identify unusual traffic flows
- Detection of bandwidth hogs or unexpected outbound traffic
- Log-based monitoring with event correlation
- Real-time alerting on unauthorized configuration changes
-
-
Infrastructure monitoring platforms often integrate with SIEM tools to support deeper security analysis. You can monitor firewall events, VPN sessions, and authentication logs from the same dashboard.
Application monitoring and APM tools help you trace performance degradation to specific services or database queries. Instead of guessing, you rely on measurable deviations and correlated alerts.
Integration with Cloud and IT Infrastructure
Your NOC must extend beyond on-premises devices. Hybrid environments require cloud-based monitoring that spans virtual machines, containers, SaaS platforms, and traditional hardware.
Tools such as LogicMonitor, Dynatrace, and New Relic provide cloud-native integrations for AWS, Azure, and Google Cloud. They collect metrics through APIs and lightweight agents rather than relying solely on SNMP or WMI.
An effective integration strategy includes:
-
-
-
- Infrastructure monitoring across physical and virtual assets
- Application monitoring for microservices and containers
- API-based cloud telemetry collection
- Synchronization with your CMDB for accurate asset tracking
-
-
Cloud collectors allow you to monitor remote regions without backhauling traffic. You maintain visibility into latency, storage performance, and autoscaling events from the same NOC dashboard.
By unifying cloud, network, and application data within your NMS, you maintain operational continuity as your environment evolves.
Modern Approaches for Operational Excellence
You achieve operational excellence by combining intelligent monitoring, structured automation, disciplined documentation, and forward-looking planning. Modern NOCs move from reactive ticket handling to data-driven, proactive control of business-critical services.
Artificial Intelligence and Machine Learning Applications
You use artificial intelligence and machine learning to detect patterns that traditional threshold alerts miss. Instead of static limits, models analyze historical performance data to establish dynamic baselines for latency, packet loss, CPU usage, and application response times.
Machine learning helps you identify anomalies early. It flags deviations in traffic behavior, predicts saturation trends, and highlights correlations across infrastructure layers.
Key applications include:
-
-
-
- Anomaly detection based on behavioral baselines
- Predictive analytics for hardware failure and link congestion
- Event correlation across network, server, and application logs
- Business views that map technical metrics to business-critical services
-
-
You shift from isolated device monitoring to service-level visibility. When a core router degrades, you immediately see which customer portals, APIs, or internal systems face risk.
This approach supports digital transformation initiatives. It aligns technical metrics with operational and financial impact rather than focusing only on device uptime.
AIOps and Automated Incident Management
You strengthen your NOC with an AIOps engine that ingests metrics, logs, configuration data, and alerts from multiple tools. The engine reduces noise by clustering related events into a single actionable incident.
Automation plays a central role. Instead of manually triaging hundreds of alerts, you:
-
-
-
- Deduplicate and correlate events automatically
- Assign incidents based on predefined rules
- Trigger remediation scripts for known issues
-
-
For example, if a service restart resolves a recurring memory leak, your system can execute that action automatically and document the outcome.
Automated incident management improves response time and consistency. It also enforces compliance requirements such as ISO 27001, where traceability and controlled change processes matter.
You still maintain human oversight. Engineers review automated actions, refine rules, and update workflows to prevent repeated faults.
Knowledge Base, Runbooks, and Documentation
You cannot sustain operational excellence without structured documentation. A well-maintained knowledge base reduces resolution time and limits dependency on individual engineers.
Your documentation framework should include:
-
-
-
- Knowledge articles for common incidents
- Step-by-step runbooks for diagnostics and recovery
- Updated network diagrams that reflect actual topology
- Escalation matrices and ownership models
-
-
Runbooks must define exact commands, validation steps, rollback procedures, and communication templates. Avoid vague instructions.
You integrate documentation into your ticketing and AIOps systems. When an alert matches a known pattern, the system links the relevant knowledge article automatically.
Regular reviews keep documentation aligned with infrastructure changes. This discipline supports audits, onboarding, and cross-team collaboration.
Capacity Planning and Disaster Recovery
You maintain service stability by combining structured capacity planning with tested disaster recovery plans. Reactive scaling leads to outages and budget overruns.
Capacity planning relies on historical utilization data, seasonal trends, and projected business growth. You evaluate:
-
-
-
- Bandwidth consumption
- Storage growth rates
- Compute and virtualization resource usage
- Application transaction volumes
-
-
Machine learning models enhance forecasts by identifying growth patterns and potential saturation points months in advance.
Disaster recovery focuses on resilience. You define recovery time objectives (RTO) and recovery point objectives (RPO) for each business-critical service.
Your disaster recovery plans must document:
-
-
-
- Failover architecture and replication methods
- Backup frequency and retention policies
- Communication procedures during major incidents
- Regular testing schedules
-
-
You test failover scenarios under controlled conditions, not just on paper. This practice confirms that automation scripts, backups, and secondary sites function as designed.
Security and Risk Mitigation Strategies
You protect your network by combining continuous security monitoring, structured incident response, and disciplined compliance practices. A NOC reduces cybersecurity risk when you detect threats early, respond quickly, and align controls with regulatory and operational requirements.
Continuous Security Monitoring
You need real-time visibility into traffic, devices, and user activity to reduce security and operational risk. Your NOC should monitor network security events, bandwidth utilization, device health, and configuration changes from a single console.
Use tools such as:
-
-
-
- Intrusion detection and prevention systems (IDS/IPS)
- Security information and event management (SIEM) platforms
- NetFlow or similar traffic analysis tools
- Endpoint and firewall log aggregation
-
-
Correlate events across systems to identify patterns that isolated alerts miss. For example, unusual bandwidth spikes combined with failed login attempts may indicate data exfiltration.
Automate alert thresholds for latency, packet loss, and interface errors to prevent network outages. Pair automated detection with analyst review to reduce false positives and maintain operational accuracy.
Continuous monitoring only works when you update signatures, patch monitoring tools, and refine alert rules as your infrastructure changes.
Response to Cybersecurity Threats
You must define and document clear response procedures before an incident occurs. Your NOC should follow a structured workflow: identify, contain, eradicate, recover, and document.
When monitoring tools detect suspicious activity, isolate affected devices or network segments immediately. Disable compromised credentials and block malicious IP addresses at the firewall to limit lateral movement.
Coordinate with security teams to analyze logs, confirm indicators of compromise, and determine root cause. Rapid containment reduces the risk of extended downtime and protects sensitive data.
After recovery, conduct a post-incident review. Update firewall rules, adjust monitoring thresholds, and close configuration gaps that contributed to the event. Treat every cybersecurity incident as an opportunity to strengthen controls.
Ensuring Compliance and Resilience
You must align your NOC operations with regulatory and industry frameworks such as NIST RMF, ISO 31000, or sector-specific standards. Map monitoring controls to required safeguards, including access control, logging, encryption, and continuous assessment.
Maintain documented risk assessments that identify critical assets, likely threats, and mitigation strategies. Classify systems by impact level so you prioritize protection for high-value resources.
Use continuous reporting and periodic audits to verify that controls operate as intended. Track metrics such as:
-
-
-
- Mean time to detect (MTTD)
- Mean time to respond (MTTR)
- Frequency of security incidents
- Recurring bandwidth utilization anomalies
-
-
Build resilience by implementing redundancy, regular backups, and tested disaster recovery plans. When outages occur, resilient architecture and practiced recovery procedures keep your services available and compliant.